GLENDOWE: I can call spirits from the vasty deep.
HOTSPUR: Why, so can I, or so can any man, but will they come when you do call for them?
I can interpret weights too, but will that interpretation be correct?
variaga 34 minutes ago
GLENDOWE: I can call spirits from the vasty deep.
HOTSPUR: Why, so can I, or so can any man, but will they come when you do call for them?
I can interpret weights too, but will that interpretation be correct?
layer8 41 minutes ago
That sounds a bit like biology; maybe AI will become like that.
dotancohen 19 minutes ago
stuaxo 6 minutes ago
athrowaway3z 43 minutes ago
orsorna 21 minutes ago
parineum 17 minutes ago
latentsea 16 minutes ago
tarruda an hour ago
awb 42 minutes ago
f311a 23 minutes ago
You can optimize a model by randomly changing its weights and validating results on your task. A monkey can type a book given enough attempts.
stymaar 21 minutes ago
solnyshok 9 minutes ago
latentsea 20 minutes ago
mccoyb 22 minutes ago
It's a blog post which received feedback from collaborators.
It hasn't gone through the academic paper lifecycle ... the authors themselves refer to it as a post and as preliminary.
I feel like I'm taking crazy pills, but can we be precise when talking about work of this form? It started with referring to arXiv pre-prints as papers, and now we're at blog posts with an academic template as papers.
A paper is a fucking paper: something which has been vetted by the scientific community, with at least some form (often, a few rounds) of anonymous review from people outside your circle of collaborators
This is not there yet, and clearly so due to the various feedback from people (including the two pushback posts on HN) critiquing the lack of discussion about the existence of these techniques in mech interp, etc?
simonw 12 minutes ago
I called it a paper here because it's by people with an academic affiliation and is of comparable quality (if not better than) many of the other "papers" we see.
I also like it when a paper isn't a PDF. PDFs are a bad way of communicating information.
(I will note that the authors themselves didn't call it a paper, their own BibTeX reference calls it a "blog post":)
  @misc{takehi2026weightspace,
    title        = {{Sparks of Weight-Space Programming: LLMs can natively read \& write neural network weights}},
    author       = {Takehi, Rikiya and Teoh, Jayden and Zhang, Alex and Khattab, Omar},
    year         = {2026},
    month        = nov,
    howpublished = {\url{https://rikiyat.github.io/blog/weight-space-programming/}},
    note         = {Blog post}
}mccoyb 7 minutes ago
But for (1, 2), just to point out, neither of your criteria would pass muster in the scientific communities who are ultimately responsible for vetting this work, right?
The ideal is: we don't accept papers at NeurIPS (or wherever) because of affiliation, and the badge of "quality" is bestowed by peer review, from other scientists.
> is of comparable quality (if not better than)
But the posts that you refer to in your own post point out several ways in which the quality is not good ...
But, in any case, I find it a bizarre choice to call it a paper when the authors themselves do not refer to it as such.
DoesntMatter22 12 minutes ago
davrosthedalek 7 minutes ago
devinprater 22 minutes ago
bsiverly 38 minutes ago
tiborsaas 29 minutes ago
The age of source code is definitely not going to end anytime soon if ever. But the future will involve incomprehensible machines editing other models in a "fairly certain" way, but we are going to need a lot of tooling to keep up with the process and not just take the model updates as "trust me bro".
badsectoracula 29 minutes ago
So i asked Qwen 3.8 27B two things:
1. What it is this network all about? I only gave it the ann.c code that implemented a simple artificial neural network library in C and the setup code that specified the network's shape but not its purpose.
Qwen 3.8 27B tried a bunch of stuff, taking the layers one by one, proding numbers through it, etc and finally figured out it is some sort of 5x5 to 2x2 filter, most likely working with pixels (i never mentioned pixels or graphics), though it wasn't certain about the exact purpose. It did rule out a bunch of uses like being a downscaler or classifier, from its behavior.
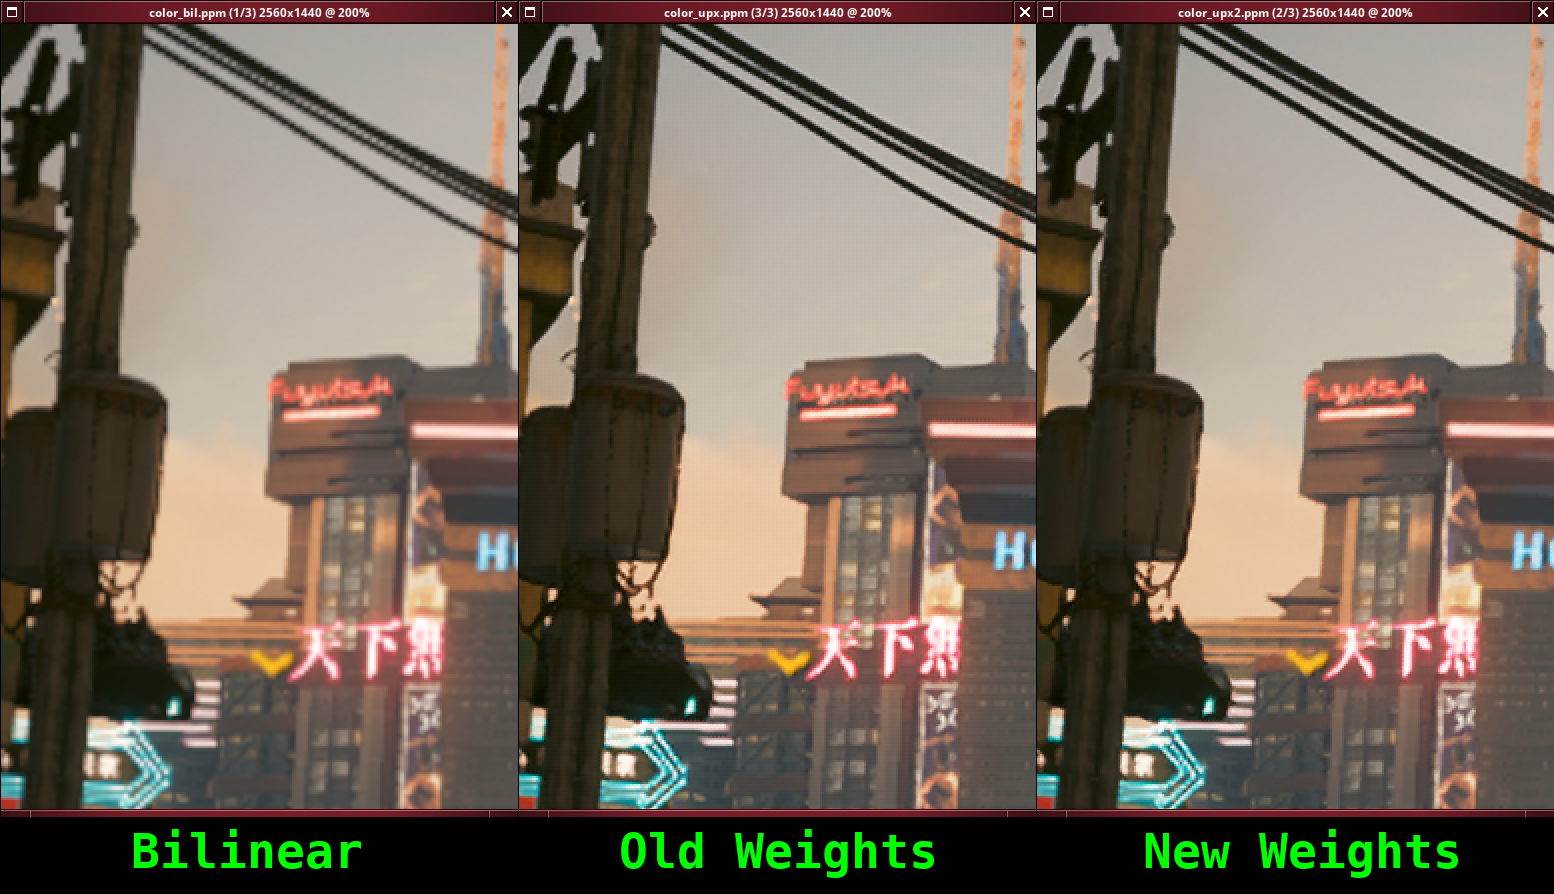
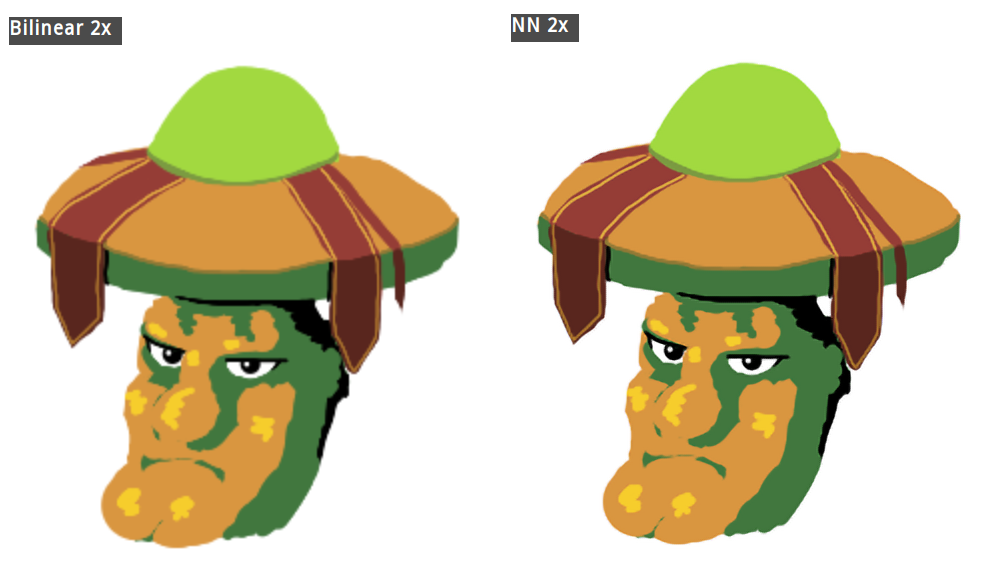
2. After i revealed what it was, i asked it if it can improve it but keep it 100% compatible with the existing program that used the weights file. And sure enough, it did improve it. I gave it the original training C code and dataset. It made a few experiments (and wrote its own training C code because it found mine too slow :-P) and ended up improving the weights. The difference[1] is small, but it basically eliminated some small noise that was always there and made some transitions less "halo-y". Of course for the purpose i wanted it (use it to upscale games in realtime) it isn't that great (too heavy) but it was learning material anyway. Though one bonus thing i noticed is that it upscales my random doodles much better than any Krita filter[2] :-P.
The above isn't Qwen 3.8 27B observing the weights directly and making sense out of them (ok actually it did seem to make some sense of the weights in the "#1" but i didn't dump the entire network to it - though thinking about it, it is only around 16384 floats so it might work). It just used a bunch of scripts it wrote in Python (and later C) but i still found it interesting to watch it go at it.
[0] https://mastodon.gamedev.place/@badsector/113765818432603610
[1] http://runtimeterror.com/pages/iv/images/a3d94ea369ff95ecf05...
[2] http://runtimeterror.com/pages/iv/images/4e29d027a8aa6e89db5...
simonw 22 minutes ago
dotancohen 12 minutes ago
> the 2x2 pixel grid that the input pixel should be replaced for a (width2)x(height2) upscale.