

Some outcomes can be annoying, but the net result is still positive, for the consumers and their data privacy at least.
ChatGPT now knows what you do on other websites via ad collector (buchodi.com)
614 pointsby lmbbuchodi11 hours ago326 comments
thih9 8 hours ago
I am once again happy that the EU is fighting practices like these via legislation.
Joel_Mckay 7 hours ago
Unfortunately, most LLM companies always were naturally an intelligence operation on civilians, and determining if they are now state-backed seems like a irrelevant detail.
Privacy has been dead for some time now. The fact is most business people never figure out how they are exploited. The modern intelligence campaigns just made it economical to hit almost everyone regardless of scale... often under some silly pretense like terrorists wanting our underpants. =3
altern8 6 hours ago
I don't know if the destruction of many industries in the EU--including manufacturing--can be called an annoyance.
All the EU bureaucrats can do is regulate, that's why it's so difficult to do business in the EU and that's why there is so little innovation over here. If Microsoft and Apple were started in the EU they would've been shut down within a week because you can't operate from a garage.
I guess that every once in a while this might have a positive outcome for consumers, a broken clock is right twice a day.
schubidubiduba 6 hours ago
I'm sure Microsoft and Apple could have been able to afford a cheap office given their parents' generous financing.
And, regarding the original topic, we wouldn't have many of these privacy issues if the US had not strategically failed to regulate its obnoxious tech monopolies
goobatrooba 5 hours ago
I don't see how that's relevant? Regulation might have limited some innovation in tech, but gdpr does not affect any of the dying industries. That's more from competition with china, companies with too much interest in giving payouts to shareholders than to innovate, and US financial industry buying most of the best players
techpression 4 hours ago
GDPR is being changed to allow tracking and AI training without consent, EU only protects people if it’s the interest of EU companies, GDPR is now too costly so it has to be dismantled in certain areas.
https://www.computerworld.com/article/4087347/european-commi...
tene80i 4 hours ago
What do you think US bureaucrats do other than regulate? The federal government drives people crazy. Have you ever tried to file taxes in the USA? It’s so complex you end up having to pay for the privilege.
The innovation gap is real but it’s not just to do with regulation. It’s a lot to do with concentrated capital networks (eg Silicon Valley). And sure, the tech giants are in the USA but it’s not like there’s no innovation in the EU. Spotify in Sweden. Challenger banks in the U.K. (included as Monzo predates Brexit). And plenty of innovation - they just get bought by US companies. Which is a financial market weakness, not a regulatory one.
fooker 6 hours ago
> Some outcomes can be annoying
I'd classify mandatory encryption backdoors as an industry crisis rather than an annoyance.
dspillett 5 hours ago
Which has nothing to do with the stalking of the adtech industry, unless you are suggesting that the EU might sell access to the keys to the likes of OpenAI?
[though you are not wrong that encryption backdoors are a backwards step on individuals rights to privacy]
Llamamoe 4 hours ago
Encryption backdoors by definition mean everybody who wants it gets hands on your data. You can't make backdoors only the "good guys" can access.
And while, sure, adtech corpos maybe won't due to the bad PR, what about the Kremlin, criminal organizations, or your insane abusive ex?
Barbing 4 hours ago
Rather tragic that less-technical folks in positions of power can find this:
> You can't make backdoors only the "good guys" can access.
incomprehensible. I’m sure genuinely so, even.
Avicebron 4 hours ago
"It is difficult to get a man to understand something when his salary depends upon his not understanding it." -Upton Sinclair
phatfish 4 hours ago
What can the Kremlin do that is worse than the tech bros? Leverage data to deliver people additive divisive content until it all boils over into the "real world" and splits society? Oh wait...
bergkvist an hour ago
Or deciding where to send a drone attack to take out a political opponent
bko 2 hours ago
It kind of does. It's like "I want an all powerful regulatory agency that can impose rules by dictat, but I only want them to do this things I agree with"
patrickmcnamara 5 hours ago
When has the EU mandated encryption backdoors?
buzer 5 hours ago
They keep trying it via e.g. chat control
tensor 5 hours ago
The US has also tried it multiple times. So has Canada. It's been shut down each time. This isn't a unique to the EU problem.
bayindirh 4 hours ago
Didn't UK had "The Snooper's Charter" as well?
Encryption backdoors is not a case of extending reach for a government, but an effort to get the capabilities back.
They were able to do that before. They just want to be able to continue now.
Note: No, I don't support the idea of backdoors. On the contrary.
RHSeeger 3 hours ago
The fact that other countries have tried to do <bad thing> does not mean it's acceptable for another country to do <bad thing>
leonidasrup an hour ago
In the end, US doesn't need encryption backdoors because most chat and email protocols are not end-to-end encrypted and the TLS data streams are decrypted in the datacenter owned by US companies.
jampekka 6 hours ago
> I am once again happy that the EU is fighting practices like these via legislation.
As long as you manage to navigate all the dark patterns and not accidentally give your "informed consent".
dspillett 5 hours ago
Malicious compliance (or as it more usually is malicious noncompliance that has not been sufficiently punished so the slimy buggers feel free to continue) is something you should blame the stalkers of adtech for, more than the EU. The legislators could perhaps have made the definitions less wavy, and been harder with enforcement, but that doesn't make it all their fault.
jampekka 5 hours ago
These problems were quite widely foreseen during the legislative process, and partly had already been exhibited by the earlier ePrivacy directive. I don't know whether it matters who's to blame, but my trust in EU being very effective in these fights in the future either is not very high.
soulofmischief 5 hours ago
Are you equally happy that the EU is attempting to mandate backdoors into technological platforms and outlaw private encrypted communication?
dspillett 5 hours ago
Copypasting my reply to someone who made almost exactly the same point in a sibling comment earlier:
Which has nothing to do with the stalking of the adtech industry, unless you are suggesting that the EU might sell access to the keys to the likes of OpenAI [though you are not wrong that encryption backdoors are a backwards step on individuals rights to privacy]
Things could be worse. It could be like most of the US where there are both no (or at least far fewer) protections against invasive behaviour of private companies and the government actively trying to backdoor private comms.
einpoklum 5 hours ago
> Which has nothing to do with the stalking of the adtech industry
It has a lot to do with the practices of the adtech industry. If privacy is protected and upheld vis-a-vis the government (or meta-government in case of the EU), it may be upheld vis-a-vis private corporations and other governments. But if the government likes to be able to spy on its citizens, it will not foster mechanisms, practices and a culture of private communications.
But - I agree that it could be much worse.
slig 5 hours ago
And the sane world is fighting the EU BS with geo blocking.
Just set up your user agent to work as you wish, isn't that simpler than have unelected, technologic dumb bureaucrats writing laws that are complex and don't solve the issue?
einpoklum 5 hours ago
Is it now? Are Alphabet, Microsoft, Yahoo and Meta's platforms and call-home products illegal for exposure to EU residents? i.e. Google, Bing, Facebook, WhatsApp, MS Office and such? Are these companies' C-suite people wanted, to be charged massive breaches of user privacy?
ljm 4 hours ago
Seeing some legitimate executive accountability would be lovely in this day and age, but even fines going into the billions of euros are still just the cost of doing business in a ridiculously lucrative space. That they also happen to dominate by oligopoly.
dmix 3 hours ago
The adtech/data broker business is still very lively in EU. The last time I read into it a year or two ago the consensus seemed to be the privacy gains over the last decade have been modest at best. There was a few big name trackers that were forced to narrow data collection but the general ad/location tracking and data broker business is still mostly the same.
https://arxiv.org/abs/2411.06862
https://netzpolitik.org/2025/databroker-files-targeting-the-...
mavsman 9 hours ago
To me, this quote just about sums it up:
> The mechanism is standard adtech. What has no precedent is running it on an AI chat product.
As someone who has been well aware of this mechanism for quite some time, I still feel icky anytime I re-read the details of it.
What a time to be alive.
clickety_clack 9 hours ago
Whenever I say something like “that’s a cool feature, but to do it you would have to build spyware”, everyone else is just like “the cat is out of the bag ¯\_(ツ)_/¯”. (I don’t build spyware, or work on projects that do).
It blows my mind that people don’t care about the world they are building with this stuff. It’s a real tragedy of the commons. People see these collaborators from different wars and regimes and think “I’d stand up against the bad guy”… well I’ve got news for you if you build spyware, you are not the person you think you are.
kltlp 9 hours ago
This is the best retort to the bag-escaping cat ever:
https://gowers.wordpress.com/2026/09/17/why-i-didnt-sign-the...
"Nothing is worse to the demise of a society, than people who want to convince you that the cat is out of the bag and will not go back in, while the cat is being violently shook out of the bag at the same time."
anonymous908213 9 hours ago
Motion to start a political platform for cats in bags. Our message is simple: Put the cat in the bag. Keep the cat in the bag.
TeMPOraL 8 hours ago
Don't force it out of the bag if it doesn't want to leave.
rapind 8 hours ago
> if it doesn't want to leave.
This is where the lawyers find the loophole to get the cat out of the bag.
wingworks 7 hours ago
Turns out, there was a hole in the bag.
TeMPOraL 7 hours ago
That was originally meant for a carry loop, but alas.
godelski 6 hours ago
That's how bags work
GolfPopper 8 hours ago
A great quote, thank you for sharing. It captures much of the five stages of denial (summarized below) in a much pithier form.
There's nothing in the bag.
The cat will never get out of the bag.
It wouldn't be a problem if the cat was out of the bag.
We cannot possibly keep the cat in the bag.
Putting the cat back in the bag is not worth trying.
ok123456 7 hours ago
No, the greatest is from the Sweet Smell of Success: "The cat's in the bag. And the bag's in the river."
mitxela 7 hours ago
And the river's in the canyon and the canyon's in the plateau and the plateau's in the volcanic shield and the green grass grows all around, all around, and the green grass grows all around.
mat_b 9 hours ago
> It’s a real tragedy of the commons
Seems more like a real tragedy of private enterprise.
We used to assume that the surveillance world would be built by government (1984). But it turned out to be equally likely to be built by the free market.
TeMPOraL 8 hours ago
The government has few uses for total surveillance, and almost all are obviously bad. Private enterprise has a million uses, most of them various degree of bad, but as a society we've been blind to this kind of badness for many decades now - for at least as long as lying in the face of your fellow humans and trying to hurt them materially has been considered a respectable profession.
titzer 37 minutes ago
It's because capitalism won the (absurd black-and-white framing of the) cold war, with America as its the biggest winner. We don't even recognize the level of propaganda that has gone into convincing us all that "markets" are the best optimizer ever designed and that profit equals morality--we just accept these as base principles without questioning them. Surveillance produces profit? Well let's have more then.
sssilver 8 hours ago
Turns out the entities you control / regulate less, tend to do things that are less in your interest and more in their own.
mitxela 7 hours ago
Well, currently the free market is the government, while the nominal government is something less powerful than that.
brookst 9 hours ago
I'm pretty unhappy with this, but are ChatGPT or Facebook really "the commons"?
ben_w 9 hours ago
They're each in different grey areas that were previously the commons.
Facebook didn't invent "talking to friends" or "showing adverts", but made itself "the place" hard enough most of the advertisers and most of the people intermediate through it.
OpenAI didn't invent "asking questions and recieving answers", not even "from an agent who knows which sites to search on your behalf"; but it is competent enough that I might have it read 50 times as many pages in a day as I myself would have read, and the sites' owners don't get real eyeballs looking at ads during this. (In my case, adblock even if I did it manually; but apply this massive increase in page hits to everyone who has their LLM research stuff).
applfanboysbgon 8 hours ago
I think any free platform with a billion people on it is, de facto, a commons. It would be great if we as a society acknowledged this and had come up with some better means of stewardship because the status quo is obviously heinous, but we've been happy to hand over absolute control of public discourse to a few trillion dollar tech companies.
nilamo 8 hours ago
Common people work there and built the tools. At any point, they could have chosen not to. Or told the boss guy it wasn't plausible. At the end of the day, we're choosing and building the world we're in, while also loudly complaining about what we choose to do.
Blaming a corporation takes away all the agency the workforce has.
clickety_clack 7 hours ago
I think the internet in general is a commons and I should be able to browse it without being spied on.
There should be general standards for what individual apps and websites should be allowed to do. There should be an expectation that the purpose of an app is what it does, i.e. a social connection app shouldn’t be an ad platform that suffers users insofar as they provide useful data to sell to advertisers.
charcircuit 8 hours ago
Your issue is you are defining spyware too broadly. This is not spying on users, but rather 2 companies partnering and sharing data to result in either a better ads system or better understanding on how ads are performing. This is a positive value to society and the commons. Wasting space in a site or app with an ad that won't convert is the true tragedy of the commons. It's a waste of time and money for all parties involved.
infinitezest 7 hours ago
Can't you see? We're just trying to build a better cigarette! Flavored to your specific tastes! You'll thank us, you'll see!
c22 7 hours ago
No ad has ever converted me yet the ad networks keep showing me ads.
charcircuit 4 hours ago
Is this due to them being irrelevant or you being stubborn against ads. It's possible you would enjoy these goods and services if you tried them out.
bluefirebrand 7 hours ago
> It blows my mind that people don’t care about the world they are building with this stuff. It’s a real tragedy of the commons.
When I ask people about things like this, I hear a lot of "If I don't build it, someone else will"
My goal isn't just to refuse to build this stuff, it is actively to resist the people who are.
I don't have much influence though
ndriscoll 2 hours ago
It's such a bizarre attitude. Like I think this stuff deserves decade+ long prison sentences for everyone involved, and they just don't care. Like imagine if mugging were legal and the people doing it just said "hey, if I don't rob you, someone else will."
mitxela 7 hours ago
Well, some people care and some don't. The people who care don't get to work on the technology.
jsrozner 9 hours ago
People think they're interacting with an "intelligence," when actually they're just getting a maximally optimized Weizenbaum feed. We're living through the sloppification of the human mind.
See e.g., https://www.science.org/content/article/ai-chatbots-are-beco...
ben_w 8 hours ago
What's the old quote from WW2?
I couldn't help but notice how each successive headline reporting our glorious victories seemed to draw closer to Tokyo.
Well. I can't help but notice how each successive headline reporting how this "scam"/stochastic parrot/"scare quotes intelligence" seems to be solving more and more things that were but a few years ago widely regarded as being indicators of high intelligence.
Being highly convinving is one of the things on that list.
mopsi 8 hours ago
It was Berlin and not Tokyo, I believe. Germany kept producing newsreels until the very end. Many of them are now on Youtube, a very interesting watch on how to frame things positively.
fiu10 8 hours ago
We need a downfall parody: "Hitler uses Openclaw".
ben_w 8 hours ago
I've heard many variants; Paris in an earlier war, too.
I try to keep an open mind about propaganda fooling me today; the people who were fooled in the past often were not fools themselves.
godelski 6 hours ago
> the people who were fooled in the past often were not fools themselves.
Being fooled doesn't make you a fool. But being unwilling to change your mind does. Being unable to admit you don't know or don't have enough information to make a strong opinion makes you a fool too.
Propaganda wants to take shortcuts, to simplify things. To trivialize. "It's so easy, you just..." because the fool is the person who already knows, the person who has nothing to learn, the person who thinks they're better than everybody else.
dylan604 5 hours ago
In the past, there were not the avenues of finding alternate sources for news. While those avenues are present today, it also allows for additional sources for propaganda. So are we any better today or not???
ben_w 5 hours ago
Not. A thousand cable channels all licensed by a government, is much the same as five broadcast channels licensed by the same government.
A million YouTubers grinding The Algorithm while secretly sponsored by various world governments, isn't much different to a thousand well-placed gossipers secretly sponsored by various world governments.
datsci_est_2015 8 hours ago
Wow, that quote goes hard.
I’m reminded that almost no one beyond a select few knew high up in the military and around the emperor knew how badly the Japanese were defeated at Midway.
Paternalistic. Arrogant. Shameful. And deeply engrained in the Japanese cultural zeitgeist (of the early-mid 20th century).
Edit: I guess it’s commonly attributed to a German citizen, but their cultures mirrored each other. Fascism falling under the weight of its own propaganda.
moth11 8 hours ago
Nobody is denying that it's effective. They're denying intelligence
A programming contest has a problem where given N < 10000, do something hard like come up with the number of primes less than N
You can come up with all sorts of algorithms that do intelligent things. But the most effective solution is to use metaprogramming to make a massive switch statement that contains all the answers
fasterik 7 hours ago
Are they denying intelligence, or are they redefining it in such a way that only humans can be intelligent? Can you come up with a definition of intelligence that would apply to crows and ant colonies, which are obviously intelligent to some degree, but not the current generation of AI systems?
mitxela 7 hours ago
Nobody knows what intelligence is. We've recently discovered a lot of things that it isn't.
fasterik 7 hours ago
Intelligence is a word we invent to describe things we see in nature. We don't "discover" intelligence like it's some natural resource. To say we know nothing about it is also a bit strange. Cognitive science has been studying it for decades. Of course it's hard to give a precise definition, but it's related to capabilities like abstraction, reasoning, planning, problem solving, etc.
infinite_spin 7 hours ago
Why would a set of dictionary definitions not suffice?
mitxela 7 hours ago
Those are distillations of existing knowledge. They are necessarily behind the status quo. "You can't call this newfangled contraption a computer, because a computer is a person!"
infinite_spin 6 hours ago
> Those are distillations of existing knowledge.
Definitions are "formal statements of the meaning or significance of a word, phrase, idiom, etc" (https://www.dictionary.com/browse/definition)
> They are necessarily behind the status quo.
The existing state or condition would be what is written in the dictionary, not whatever personal definitions you've constructed.
> "You can't call this newfangled contraption a computer, because a computer is a person!"
Seems like a straw man. A computer is not a mammal, no matter how much you twist a set of definitions.
quicklime 5 hours ago
> A computer is not a mammal, no matter how much you twist a set of definitions.
I’m not the person you replied to, but I believe they’re referring to the occupation of “computer”:
https://en.wikipedia.org/wiki/Computer_(occupation)
So yes, at one time all computers were mammals.
The people who write dictionaries generally take a descriptivist approach, that’s why slang terms enter the dictionary after they start to become popular.
The state of the art of human knowledge would be another step ahead of the common use of any language.
infinite_spin 5 hours ago
That's an interesting take, and I can see how "computer" could refer to a human a hundred years ago, but they also mentioned "status quo", which should indicate that a reasonable person should use a modern definition.
quicklime 5 hours ago
Again I’m not the person who wrote the comment, but I think they were exaggerating for effect and maybe lost the audience in doing so. While “computer” has meant the same thing for many decades now, the term “intelligence” really does seem like a moving goalpost?
infinite_spin 4 hours ago
I think it's only a moving goalpost if you can show that the goalpost has moved with a new definition that fits our current usage of it. The people saying "this isn't intelligence", and then claim "we don't even know what intelligence is", are encouraged to offer such a definition.
mitxela 4 hours ago
Several decades ago, "computer" was a moving goalpost due to the invention of the electronic computer, and then the digital computer.
infinite_spin 2 hours ago
yet those movements came with clear definitions. If you have a new definition for intelligence, which isn't just designed as a definitional dodge, then please provide one
mitxela 4 hours ago
Imagine you're the first one to invent a digital electronic computer. You call it a computer, and I go on Tinkerer News and post (by carrier pigeon) "ummm akshully computers are people????" - which one of us would be adding value and which one subtracting it?
handoflixue 5 hours ago
> They are necessarily behind the status quo.
That seems like a really bizarre way to describe a tool that solved an open Millennium Prize Problem. They are, empirically and repeatedly, ahead of the status quo.
So if your argument depends on them being behind the status quo, reality has already disproven it multiple times over.
mitxela 4 hours ago
I wasn't aware a dictionary definition solved a Millennium Prize problem. Which one and how?
4fddd3 4 hours ago
What we know is intelligence is definitely comprised of the trait of adaptability.
E.g. humans get exposed to new LLM model - yeah its powerful - 1 week later - eh, that thing? Yeah it's whatever. I'm still employed.
The human's ability to adapt so efficiently is mind-boggling - so much so it pi1sses sam altman and dario off.
ben_w 7 hours ago
How many examples you need to get good.
Don't misunderstand: I'm happy saying AI models "think" or "have learned a thing", and for in-context learning I'd call them smart even by this definition…
…but also, any living creature that needed as many examples as machine learning currently needs, would starve to death before figuring out how to eat.
While training, machine learning processes (not just LLMs, also applies to e.g. self driving cars), are really really stupid and only make up for this by being really really stupid really really fast.
To what I wrote upthread: the "victories" of humanity over machine keep getting closer, but we have yet to wake up one day in great confusion as we find an entire city is no longer in communication with anyone, nor finding ourselves in a state of utter disbelief when the reports come in that the city stopped communicating because it is entirely gone.
fasterik 6 hours ago
If we're including the training process and not just the final product, why shouldn't we include the billions of years of natural selection encoded in DNA sequences?
ben_w 6 hours ago
Because our evolutionary environment doesn't contain cars, poetry, calculus, Star Craft, hamburgers, touch screen computers, or doors, and yet we are able to learn these things with (relative to a computer) very few examples.
Most of the effort of evolution was making cells work at all, and even then it's a bit weird, e.g. no plant or animal produces vitamin B12 and we all get this from some bacteria and archaea.
And evolution is kinda hard to time right: bacteria can reproduce in minutes, humans in decades, but only mutations that survive reproduction can be passed on. This makes it even starker as a difference: bacteria had order of 1e13 generations to become multicellular, while human DNA had about 40,000 generations to cope with fire, 220 generations for evolution to do anything with the invention of the wheel, and one generation to cope with the invention of Minecraft.
The analogy here would be: DNA is to our brains like a VN replicator bootstrapping a computer all the way up to a bare-metal-no-OS untrained model, and perhaps a few crude "hard coded" modules like a smiling-face-detector. It's a lot, but it's also missing a lot. If biology used the models and training processes that are state of the art in ML, it would take around a millennia to talk like a child and still fail the Sally-Anne test, and million years or so to pass a degree.
fasterik 6 hours ago
I think you're underestimating how much knowledge about the world is encoded in human DNA, especially in the structure of the human brain at birth. It also depends how we count the "operations" used to train a human adult, even if we ignore the evolutionary history.
I'm still going to deny the premise of your argument, becasue I think we should define intelligence in terms of capabilities. If a system can discover a cure for cancer or solve P vs. NP, it doesn't matter how many FLOPs it took to train.
ben_w 6 hours ago
I can literally point to how much information is encoded in our DNA, because it's four bases (so 2 bits per base pair) and ~3.1 billion base pairs. 6.2 gigabits total, or slightly less than 1 gigabyte.
A 1 gigabyte LLM isn't going to impress anyone with what it can do.
About 99% (depends who you ask) of our DNA is shared with our nearest primates. Like us, they can learn to use touch screens, but also like us they won't find touch screens in their natural environment. Dogs can be taught to drive cars (just about), but again, not natural environment.
> I'm still going to deny the premise of your argument, becasue I think we should define intelligence in terms of capabilities. If a system can discover a cure for cancer or solve P vs. NP, it doesn't matter how many FLOPs it took to train.
We can define it in either way. I think both are valid, because plenty of people mean each of these two things when discussing AI in particular. As I referenced in the other branch, these submarines sure can swim fast.
But at the same time, they have a lot of gaps. This is because some experience needs the real world: just as nine women can't make a baby in one month, a transistor running a million times faster than a synapse can't make a month-long cancer experiment happen in 2.6 seconds.
This dependency on data, and that state of the art ML is bad in specifically this way, is why Tesla's self-driving cars, despite having had around a trillion miles of real-world experience today, still come with steering wheels (even at least some of the Cybercabs, despite the big thing of this model supposedly being not needing them, though with Musk and his promises you should only count the Cybercabs when they actually ship and not just press releases).
fasterik 5 hours ago
Note I used the word knowledge, not information. A random string can also contain 1 gigabyte of information.
Imagine an alien that matches your abilities across every domain, but has a 10 billion year training period, something many orders of magnitude more expensive than an LLM. I simply don't believe that alien is less intelligent than you.
We also don't expect humans to be competent in every domain. Most humans suck at most things. We will usually call someone intelligent if they excel at solving problems in one or two narrow domains.
ben_w 5 hours ago
Information is an upper bound on knowledge.
> 10 billion year training period, something many orders of magnitude more expensive than an LLM.
I'm saying both definitions are valid definitions, they both point to important and different things: skill now, vs. how hard it is to get new skills. Some would describe it as "crystallised intelligence vs fluid intelligence".
I think it's important that any arguments are over the thing in dispute, not the label for that thing. Don't mistake the map for the territory.
Anyone who says "AI is stupid" by the first definition, what it can do, I think is making an error: they are already wildly super-human in at least some areas, if not generally.
Anyone who says "AI is stupid" by the second definition, how many examples they need, I agree with: there is a lot they are not currently able to learn even though it is easy for us, because the data they would need to do the learning on does not exist at the scale they need.
Also note: examples, not years. An alien intelligence whose synapses trigger 10 times faster or slower than mine (or ten million times faster or slower than mine), but who gets as much as I do out of each book or conversation, is my equal by the second definition.
fasterik 5 hours ago
I wouldn't say that information is an upper bound on knowledge because we don't measure knowledge in bits. The number of possible sequences of N bits is 2^N and knowledge involves selecting the sequences that are useful in some way. I don't know how to quantify it, but in principle it could be much larger than N.
I don't think I agree with your characterization of the second definition. Time scales matter. It's not much use to be able to solve human-scale problems if it takes millennia. And it only takes months to train an LLM to the level that it can solve cutting-edge math problems.
godelski 6 hours ago
We do.
There's a lot of innate knowledge but all neuroscience demonstrates how incredibly flexible the brain is. Brains constantly learn and rewire.
Here's a few things that I think show how crazy it is AND stress those points
  - people that have had corpus callosotomy (brain cut in half) *may* be indistinguishable from a normal person. Depends on how young you were when you underwent the procedure
    - true for most brain injuries
    - can even include the frontal cortex
  - you can learn to ecolocate
  - people with Aphantasia are indistinguishable from others
  - people without an internal monologue are indistinguishable from those with one
  - people can learn to use prosthetics
    - even without disabilities
    - or look into MRI scans with tool use
We are constantly learning. You aren't just born with your knowledge and it stays static. We are extremely proficient at metalearning (learning how to learn, few shot learning, zero shot learning [0,1]). Our brains are constantly rewiring, able to heal from traumatic damage.
I could go on and on. Does information pass down through genetics? Of course! But that's far from the whole story.
I'm tired of people trying to make AI sentient by making humans robotic. Stop trying to trivialize everything and be okay not knowing the answer to everything. You're human, you're designed to learn and explore, not sit and argue from an armchair
[0] and I mean these in the original sense. Not in the sense that you train on a billion examples of labeled animals and then congratulate yourself on your ImageNet-1k held out test performance. That's not zero shot, that's just a test set
[1] I can literally make up words and you'll understand them. Or use words in novel ways. That's literally how slang works and how new words come to be. Don't be a walibanut ya glufus. Read some SciFi
keypusher 6 hours ago
Millions of years of evolutionary knowledge hard-coded into human systems, then it still takes 15+ years of us learning by example before we start to come online and be able to generalize solutions from a limited set of examples. I'm not sure this is as strong of an argument as you think it is. It also doesn't really matter when "we are trained differently" has no direct bearing on the end result.
ben_w 6 hours ago
We invented controlled fire perhaps a million years ago; at a generation gap of 25 years, that's 40,000 opportunities for evolution to pass on a mutation that does anything. Written language is around 210 generations old, the capacity to read and write isn't present in our nearest living relatives amongst the primates, and our various languages are wildly different to each other: the skill itself isn't evolved, though the capacity to learn the skill is.
If humans learned like ML systems learn, (biblical) Methuselah would still have been failing the Sally-Anne test on his supposed deathbed at 969 years old, like some of the smaller early LLMs did.
> It also doesn't really matter when "we are trained differently" has no direct bearing on the end result.
The question was to ask for a definition such that AI could still count as "not smart" compared to humans. This fits.
It's also why they're spiky intelligences, which I'm happily using right now to write code for me, but also do not trust in the slightest to identify the weeds in my garden. These submarines sure do swim fast*, but they're also very much disqualified for the Olympics.
lambdaone 6 hours ago
This is classic AI goalposts-moving.
OK, they can play chess, but that's not real AI - can they write poems? OK, they can write poems, but that's not real AI - can they compose music? OK, they can compose music, but that's not real AI - can they translate languages? OK, they can translate text, but can they do maths? OK, they can do maths, but can they solve a Millenium Prize? <-- we are here
janalsncm 4 hours ago
Imagine meeting a person who could do all of those things.
“I once met a person who could beat any grandmaster in chess, translate any language, and complete international math Olympiad problems. He couldn’t solve any Millenium problems though, so I’d say he was a midwit at best.”
janalsncm 4 hours ago
On your particular point about finding the most “effective” solution, this is something that I expect agents to be very good at.
When AI does it we call it “reward hacking” but when humans do it we call them clever.
gxs 7 hours ago
Or both, you know. An intelligence that also spies on you
Why is it so black and white?
spying_lg_tv 7 hours ago
How are you so dumb at this point in the game? It’s not “intelligent”…
gxs 6 hours ago
Create a new account to be able to say what you just said
Your kind is what makes the internet shit, not AI
trial3 7 hours ago
humorously, my regular iPhone on a residential home network failed the cloudflare AI bot detection and i can’t read that article
mitxela 7 hours ago
People don't believe me that Cloudflare blocks more humans than bots. They see in the dashboard "number of bots blocked" and it's like their brain turns off.
dylan604 5 hours ago
If you don't also display how many humans were blocked, how they know?
jayknight 4 hours ago
Surely there are more bots than humans.
brianleb 7 hours ago
Could you define (or link) to what "Weizenbaum feed" means/references? Too obscure for me but I'm interested. Thanks.
fweimer 7 hours ago
Likely a reference to ELIZA: https://en.wikipedia.org/wiki/ELIZA
handoflixue 5 hours ago
Are there really people that can't tell the difference between ELIZA and something that can solve open Millennium Prize Problems in math?
joquarky 5 hours ago
Their ego doesn't let them see the difference.
mapontosevenths 5 hours ago
Or perhaps their wallets. There are a lot of programmers here. Some of them think that AI is the death of their profession, rather than a change in it.
"It is difficult to get a man to understand something when his salary depends upon his not understanding it." - Upton Sinclair
jsrozner 5 hours ago
I, uhm, think this idea would apply in both directions.
jsrozner 5 hours ago
It turns out, oddly enough, that it's possible for it to be both. AI can simultaneously be used to destroy the commons with slop and also make contributions to new math (though isn't the jury still out on whether part of the idea was stolen from human mathematicians?)
handoflixue 5 hours ago
What does "destroy the commons with slop" have to do with ELIZA comparisons?
esikich 4 hours ago
Yes, AI threatens the folks who think that knowing how to write JavaScript or C makes them smart and being smart is their entire identity.
daveguy 4 hours ago
LLM chatbots are software designed to manipulate, addict, and mine data. Just like social media before it. But anyone who bothers to read the output in a domain they understand will discover they aren't all that no matter who OpenAI steals research from.
angoragoats 4 hours ago
Humans solved the open math problems.
MisterMunchkin 4 hours ago
They had to solve the car wash problem by hardcoding the solution in. The AI equivalent of adding another IF statement.
They had to steal the work of researches solving these open problems and then rewrite their solution. The AI equivalent of fraud.
thinking_cactus 2 hours ago
Meh. The car wash problem is an underspecified statement. It's like, hey, I just popped into existence and someone asked me if they should drive to the car wash nearby.
It's not an insane assumption that the user isn't dumb and has some other reason to be asking the question other than it being a trick/stupid question (duh, if you want to wash your car you need to drive it to the car wash!). Taking it as some ultimate measure of intelligence simply doesn't make sense to me.
myaccountonhn an hour ago
The critiques of AI laid out it Computer power and human reason are mostly still valid.
gloryjulio 8 hours ago
A lot of the Meta/Google folks jumped ship to Openai/Anthropic. This kind of work is expected
saghm 18 minutes ago
Yeah, this is just standard third-party cookie functionality, which has always been sketchy. It honestly seems like it was only possible by accident; browsers have long prevented sites from reading cookies from other domains, but it seems like the people working on early specs might not have considered the ramifications of being able to set cookies for domains other than your own. A couple decades ago it might have seemed like no one would have any reason to set a cookie they couldn't read.
cma 13 minutes ago
> What has no precedent is running it on an AI chat product.
Meta?
duhhhhh1212 6 hours ago
https://www.pangram.com/history/c3ad864f-2a50-4785-a0ef-71f2...
why not use your own words? If you are gonna ai generate this blog, just post the prompts instead.
handoflixue 5 hours ago
There's a certain irony in linking to someone else and then saying "use your own words". If we follow that, we get a pretty obvious answer: sometimes someone else can express it better and faster.
Most people do not, in fact, want to read raw prompts.
crmd 5 hours ago
It’s misleading to post model output on a blog, especially when the about says
> This blog is where I write about what I find.
Why not simply include a disclaimer that it was AI model output not his own writing? Because humans don’t like AI writing and the article wouldn’t be featured on as many tech news sites. Hence the sin of omission, the choice to mislead.
scared_together 5 hours ago
Are you referring to the Pangram link? I’d consider that akin to a reference supporting the comment’s point, not a substitute for the comment’s point.
> Most people do not, in fact, want to read raw prompts.
I wonder if this is really true, and if it will remain true for long. Have you observed someone read another person’s raw prompt? Or observed someone submit both their prompts and their LLM output for review?
Personally I’d be curious about the prompts for a lot of top HN articles which are LLM-generated. It would say a lot more about the human operator’s intent and thinking process compared to the LLM output.
A coworker who spoke English as a second language once screen shared their Claude session during a code review, and it was interesting that their prompts were all in their native language. The guy wasn’t writing an article, and I didn’t understand the prompt anyway, but I still found it interesting as a glimpse into how he uses LLMs.
For this particular article, if the prompt was initially a series of bullet points that wouldn’t be so bad. If there were multiple prompts spent editing and rearranging the article that would be an unusual work by pre-LLM standards. However I’d suggest that instead of dismissing the idea, we could embrace “raw prompts” as a kind of new medium, to cross the divide between pro-LLM and anti-LLM readers.
Sharlin 5 hours ago
Having an LLM generate major parts of text that you (whether explicitly or lying by omission) claim as yours is dishonest and plagiarism, and it baffles me that many people just don't seem to mind or see anything problematic about it.
devilsdata 5 hours ago
If you can't be bothered writing it, why should I be bothered reading it?
nicce 4 hours ago
> Most people do not, in fact, want to read raw prompts.
I also wonder what is the energy consumptiom difference between the prompt and fetching website.
abhis3798 5 hours ago
How is this adding to the discussion? The post in itself is quite informative.
duhhhhh1212 5 hours ago
Do you constantly want to be reading ai-generated content on this site? If so, why not just stay on chatgpt.com and ask it to generate what hackernews.com would look like today? It's adding to the discussion because I feel like the author broke a social contract by probably putting less effort into writing this than I did reading it.
nzealand 3 hours ago
> the author broke a social contract by probably putting less effort into writing this than I did reading it.
I seriously doubt that.
First, the author documented a substantial effort (testing, emails, references to documentation.)
Second, I also used AI to evaluate if this was written by AI, and my AI said it was not.
> Broken sentences that a model wouldn't produce. "The value is while you are on ChatGPT and tied to your ChatGPT account" is missing a word. "Loading that code, sends __obi to OpenAI" has a comma splitting subject from verb. "By the virtue of loading the tag the identifier is disclosed" is non-idiomatic. LLMs are fluent to a fault; these are the fingerprints of a fast human writer, possibly a non-native English speaker.
Third, I read it. Whilst it is not well written, it is succinct. It is novel. It has a few detailed references. It lacks many of the hallmarks of AI. It makes a number of novel yet falsifiable claims.
I challenge you to come up with a blog post with these qualities that can be created in under 15 minutes via AI.
While I commend you on actually using an AI tool to validate your assumption, rather than simply hurling AI slop accusations based purely on vibes, I do think you and your AI tool are likely incorrect.
eventualcomp 2 hours ago
> created in under 15 minutes
This is an artificial constraint that does not serve the reader. Where did the 15 minute constraint come from?
Sharlin 5 hours ago
Having an LLM generate major parts of text that you (implicitly or explicitly) claim as yours is dishonest and plagiarism and should be brought to readers' attention, and it baffles me that many people just don't seem to mind or see anything problematic about it.
slig 5 hours ago
Why comment if you have nothing good to say?
angoragoats 5 hours ago
Hello Pot, I would like to introduce you to Kettle.
slig 4 hours ago
Another one.
angoragoats 4 hours ago
I retract my previous comment as it was not an instance of the pot calling the kettle black; the comment you replied to was way more helpful and informative than yours.
slig 4 hours ago
Thanks for keeping me informed.
ljm 5 hours ago
Why would you want n people to compute an AI prompt independently instead of reading the output once? And why would that be better?
At least criticise the article on merit and not some 'let me google that for you' high horse. If it's slop it's slop, but let the votes speak for that.
xmprt 5 hours ago
> OpenAI's ad collector at bzr.openai.com sets a cookie called __obi, scoped to .openai.com
This sentence is way too much detail and it's literally the first thing you read. I can pick apart most of the sentences in the article. Another one:
> Across 932 decoded sync tokens, 736 carried subject_type: account_user and 196 carried anonymous
This sentence is pointless. What matters to proving that "It works when you are logged out" is to show that the identifier is stable. Why does the reader care about the actual counts.
AI has a tendency to do this which makes AI generated text a lot harder to read. The raw prompts likely don't have the specific websites and cookie names because that's not relevant to the reader or writer for that matter - it's a footnote at best.
ljm 4 hours ago
I understand this, I just think that 'share the prompt' will never get a result. Either the prompt is total dogshit or you learn that it was written in a certain way to create a narrative. That's information the author will never reveal.
Like I say, slop is slop. It's easy to detect. This post and the OP's actual website is basically just a few AI blog posts. I would just treat it as spam and disengage.
scared_together 5 hours ago
Not everyone would actually send the prompt to an LLM. Some would have the opportunity to see the prompt as its own artifact, devoid of LLM-generated “hallucinations”.
> let the votes speak for that.
The comment you are replying to got a fair number of votes too… Having somebody run a Pangram check saves n people the trouble of doing the same.
ljm 4 hours ago
I said this in another comment, but an AI blog author is never going to reveal their 'source' that way. Mostly because it'd be a rubbish prompt or one that is loaded with a predetermined conclusion.
I think you have to take the output as read and decide accordingly. If it looks like low effort AI writing then it's not much better than spam.
I think the the top-voted post being all about the provenance of the article says something about where HN's voting mentality lies - we are not prioritising the substance of the post but how it was produced.
siquick 5 hours ago
> just post the prompts instead.
Why would anyone want that?
duhhhhh1212 5 hours ago
Because I want to read the author's words, not claude's, chatgpt's or grok's.
Note to folks who have this same thought (seems like many given other comments). Why are you on this site if you aren't here for human-created content? If you want AI generated blogs/posts there are plenty of sites like linkedin, twitter, chatgpt, and claude that will give you meaningless content with a press of a button.
nicd 4 hours ago
I'm personally here for thought-provoking, high-quality content. To quote the HN guidelines, "Anything that good hackers would find interesting."
AI content is typically lower quality, but I'm not opposed to AI-aided content just on the principle of the thing?
jhhh 2 hours ago
Part of the reason I stopped using facebook is, beyond the content being terrible, it was super creepy that they would show me ads for things I searched for on other sites. I even have facebook in its own container, but it must have some additional tracking available because it would still know that I was searching for exact clothing brands, college apparel, trips, etc. I already saw gemini integrate some information about me into an answer recently and am getting the feeling I won't be using it much longer. I'm not surprised openAI is going to try to make money similarly. Gross.
stingraycharles an hour ago
This is a very common practice called retargeting / behavioral targeting and has existed for about 2 decades at this point. Facebook is hardly the only company that does this.
Modern browsers are more strict towards third party cookies, but there are plenty of ways to work around this.
NothingAboutAny 27 minutes ago
I was talking about changing banks with my spouse, the following two weeks I get podcast ads and Samsung TV ads about the bank I mentioned.
I use all the usual off the shelf "dont track me" stuff like a pihole and a "resit fingerprinting" Firefox fork and a VPN and everything else.
I'm not amazed it still somehow got me, just sad.
saghm 14 minutes ago
I've never worked in adtech (and hopefully never will), but the first idea that would pop into my head for trying to track people who sequestered their cookies like this would be to have the sites who put in the third-party cookies include the IP address. If only one Facebook account is known to log into that IP, you know who it belongs to, even when there's no active login.
I imagine that people actively trying to make money off stuff like this would have come up with plenty more ideas than just this one.
luke5441 9 hours ago
MDN lists how different browsers prevent this: https://developer.mozilla.org/en-US/docs/Web/Privacy/Guides/...
Firefox, Brave and Safari do. Chrome and Edge do not.
skybrian 8 hours ago
Not an accurate summary. That link actually says:
> Google Chrome doesn't block third-party cookies by default, only in Incognito mode, or when users explicitly set it to block third-party cookies via chrome://settings.
Looks like the settings let you block all third-party cookies and add exceptions for specific sites, which seems a bit awkward but could be made to work.
Alternatively, you could run OpenAI in its own profile, or look into what extensions might do.
nicce 8 hours ago
I think that if they don’t block by default, is quite significant. Chrome + Edge has superior marketshare and then add the % people who have no idea what these mean and don’t change defaults.
gruez 8 hours ago
>Looks like the settings let you block all third-party cookies and add exceptions for specific sites, which seems a bit awkward but could be made to work.
The fear over blocking third party cookies breaking stuff is severely overstated. I have it disabled by default and I don't think I've ever seen any website breakages. The most is office365 nagging me to click on links so it can authenticate across domains.
troupo 8 hours ago
> Google Chrome doesn't block third-party cookies by default, only in Incognito mode
And the focus on cookies only is also intentionally misleading. Tracking is not just cookies. Chrome will track you in Incognito mode.
Andrex 6 hours ago
I was going to say, wasn't this supposed to be the default in Chrome by now? But Google reneged on it two years back:
https://www.cbsnews.com/news/google-third-party-cookies-chro...
This disgusts me more than any of their recent news. There needs to be a lot more pressure on them to phase this out.
Maybe this article will be the small snowball that gets that started...
zulban 2 hours ago
Not sure what point you're trying to make. Do you think politely asking an ad company to disable ads on their browser is a reasonable thing to spend your effort doing?
mokre 6 hours ago
That’s not fully protect you.
They still can match short living third party identifiers with their domain cookie or device_id from app.
It is not 1-1 matching but works relatively good with modern itp.
luke5441 4 hours ago
This would work for an ad shown on ChatGPT and then clicked on (or in the ChatGPT app).
But it would not give ChatGPT information about which other sites are visited.
Of course there would be non-cookie options like fingerprinting (also via IP) that would allow tracking non-the-less.
So you might be talking with OpenAI about your marriage problems and then based on the IP the OpenAI ad network would start showing ads for divorce lawyers on unrelated sites you browse to that display ads.
The solution to that would be using a VPN.
prologic an hour ago
Why must every piece or technology, every software service or cloud "thing"™ devolve into Advertising?! That's it, I'm out. No more ChatGPT for me.
noisy_boy an hour ago
What I'm more interested is in that the entire model is based on us being reduced to walking talking living breathing coin wallets. It's like a planet scale game where the companies are the players and we carry the loot.
We use a great chunk of our lifespan to procure the coins and every company is designed to extract as many coins from us as possible.
What happens to this game/real world when this model collapses? We can't procure, they can't extract. What then?
prologic an hour ago
I agree, precisely. I'm kind of sick and tired of it to be honest. What if we collectively (humanity that is), just quit? What if we all stop playing? (I think you're saying this) -- But seriously. Both OpenAI and every other place (gawd I hope others aren't doing this) need to figure out their business model fast™ and make it a viable business without devolving into this tracking, marketing and advertising bullshit some of us have only seen far too often -- that have driven us away from things like Meta/Fac** and others...
1saadcodes 9 hours ago
The technology isn't anything new but, it's the context that makes it so uncomfortable.
People have very different "expectations" of privacy when they're having a conversation with an AI VS when they're browsing something like Facebook
Not to mention Facebook is free whereas you pay for a GPT subscription
ben_w 9 hours ago
I'm old enough to remember when people had expectations of privacy on Facebook, when the discovery that they didn't made for schocked headlines.
bigyabai 8 hours ago
You know, Facebook, built by the guy who scraped college databases for personal information without the student's permission.
There was never any expectation of privacy if you knew Zuck's history. Facemash almost got him expelled for violating individual privacy.
ben_w 8 hours ago
That's the trick: in the early years, most people didn't know Zuckerberg's history.
bigyabai 7 hours ago
Caveat emptor, the saying goes. If people don't have an appetite for privacy, don't expect them to take a principled stance based on outrageous headlines.
It's not a coincidence that federally backdoored spyware like Windows is the most popular operating system in the world. I too remember the shocked headlines of the Snowden revelations, and ten-plus years later I work shoulder to shoulder with people that couldn't possibly care less. There is no expectation of privacy, HN too quickly extrapolates it's own virtue signalling to normal people that enjoy using spyware like TikTok, Facebook and Windows.
palata 8 hours ago
Back then I didn't have expectations of privacy, I think. I just didn't have a notion of privacy. I didn't think the internet was hostile, I believe?
shepherdjerred 8 hours ago
ChatGPT is also freely available
throwaway219450 5 hours ago
I don’t think there is any consistency in behavior. People react viscerally to the unproven belief that the Facebook app records conversations. They’ll also happily buy big TVs despite the fact they’re very much listening to you and we have solid evidence that it’s for ads or residential proxying. Most people have no idea how ads “follow” you, or how companies can figure out what you talked about by connecting the dots from other user metadata.
einpoklum 5 hours ago
> Not to mention Facebook is free whereas you pay for a GPT subscription
Recalling the now-old adage: Facebook is only free if your time and privacy are worthless.
what 4 hours ago
>Not to mention Facebook is free whereas you pay for a GPT subscription
The overwhelming majority of users do not pay and use the free service.
exceptione 9 hours ago
The surveillance economy hits again. The only business model they can think of. Combined with state capture this gives unprecedented power over the Average Joe, who will hand his life, his soul and his vote to Big Brother without a thought.
robots0only 5 hours ago
This is incredibly sad, with google you can atleast use the argument that search was free (which is still weak IMO). But with OAI collecting indiscriminate data on paying customers is just incredibly sad.
gizmodo59 4 hours ago
You can pay for whatever Google service and they still collect this data. Same with meta subscription.
Legend2440 9 hours ago
So basically the same kind of tracking that Facebook, Google, etc have been doing for decades?
emptybits 9 hours ago
Similar, yes, but some people are paying OpenAI to be part of this business model, unlike typical free-riding Google and Facebook users.
troupo 8 hours ago
Derogatory "Free-riding users". "Free riding users" should have the same privacy as the paying ones.
rangestransform 6 hours ago
Will the government pay OpenAI to run an ad-free free tier?
upboundspiral 4 hours ago
The government could pass laws that prevent advertising becoming mass surveillance and stalking.
troupo 4 hours ago
Ads don't require pervasive and invasive tracking, and surveillance that Stasi would have wet dreams about.
what 4 hours ago
Kind of silly. You have to pay somehow. Either pony up cash or pay with your eyeballs or data. But I doubt paying will give you privacy either.
theptip 8 hours ago
If you pay OpenAI full price, this machinery should never be used. The only paying customers getting ads are the “ad supported” tier.
I think you can easily imagine a future where the subscription model token subsidy ramps down and is replaced by ads, but it’s important to use precise language about the current state of the world.
emptybits 2 hours ago
Yes, “Go” plan users pay and also receive ads. They pay less.
gentlewater 8 hours ago
Which has really only been accepted because 99% of people don’t understand how it works. Hard to be outraged by something you can’t see or understand. In my book, the practice is akin to malware. I recently opened a website for an AI service in incognito mode, because I didn’t care to have it in my search results. Despite avoiding third party cookies here, the site still fired off a tracker to Meta, who then correlated my home IP address with my Facebook account, and filled my feed with ads for this AI service. When I was tracked like this despite a somewhat informed defense, which defense do normal people have against this? None.
latexr 7 hours ago
https://en.wikipedia.org/wiki/Whataboutism
The fact that others do the same doesn’t make any of the cases excusable.
rvz 7 hours ago
Yes. But there is no surprise given that OpenAI hired lots of ex-Meta and Google employees for that reason.
jhhh an hour ago
Yes, the thing that many people do not like is now being done by yet another company.
jazzcomputer an hour ago
I'm not really a code person, but would I add these filters to UBlock?
||bzr.openai.com^$third-party ||bzrcdn.openai.com^$third-party
sigzero 9 hours ago
Why does ChatGPT need to know that? That should be illegal.
jsrozner 9 hours ago
Because it's another surveillance adtech company from SillyCon Valley. Duh.
SoftTalker 9 hours ago
It turns out that the only way to make money online is ads.
Nobody is going to pay for ChatGPT. They'll just use the ad-infested version, like they do everything else online. Well some people will pay, but not enough to justify the insane amounts of money being poured into it by investors.
coliveira 9 hours ago
Governments will also pay for the tracking capabilities, as they're already doing to Google, Amazon, Facebook, etc.
SoftTalker 9 hours ago
Yes, I should have said "ads and tracking" good point.
jsrozner 9 hours ago
A bigger problem is that it will be impossible to know when you are seeing an ad: political groups (or the government, perhaps) will partner with openAI to subtly express different values.
It's still an advertisement, and the underlying marketplace is similar (pay for access to change behavior).
The best uses of AI will be surveillance, propaganda, cyberterrorism, and automated military tech.
See, e.g., https://www.nytimes.com/2026/09/18/technology/iran-china-aut...
andsoitis 9 hours ago
> The best uses of AI will be surveillance, propaganda, cyberterrorism, and automated military tech.
I think it is more insidious than that. AI shapes how people think not just what they think.
eli 9 hours ago
Something like it is basically a requirement if you want to see digital ads. Advertisers want to know how many people who saw/clicked their ad went on to make a purchase.
Safari and Firefox should isolate the cookie by default.
kibwen 9 hours ago
>> Why does ChatGPT need to know that? That should be illegal.
> Something like it is basically a requirement if you want to see digital ads.
So to summarize, yes, it should be illegal.
gruez 8 hours ago
>Safari and Firefox should isolate the cookie by default.
That's what firefox's total cookie protection (enabled by default) does.
driverdan 8 hours ago
> Something like it is basically a requirement if you want to see digital ads.
It is not a requirement and no one wants to see ads.
troupo 8 hours ago
> Safari and Firefox should isolate the cookie by default
Doesn't mean you won't be tracked by about 15 other means.
dofm 8 hours ago
To make the only consumer revenue that will really ever be available.
Remember they once predicted it would be 50% of their income.
This is the only way they get there.
charcircuit 8 hours ago
Attribution is a core part of building an ads system.
tgsovlerkhgsel 9 hours ago
This is why you use Firefox that keeps the cookie jars separate (by default, AFAIK). That should prevent this specific implementation, shouldn't it?
tgv 9 hours ago
There are other ways to track. Containers offer a bit mote protection, but the IP address is still visible (unless VPN).
armadyl 8 hours ago
Containers don’t offer a benefit over normal browsing for this, Firefox already blocks and isolates third party cookies.
tgv 7 hours ago
Caching is also a tracking signal.
mitxela 7 hours ago
Caches are also isolated. One of the reasons you shouldn't use a JavaScript CDN any more.
JoshTriplett 9 hours ago
Yes, it should. But this is also why you use uBlock Origin to block tracker scripts.
consumer451 8 hours ago
Firefox is my daily on desktop, but on mobile it's Safari. I finally got around to installing uBlock Origin Lite on iOS. I used to run the Firefox version on iOS, but that was discontinued long ago, and I never replaced it. I feel like a bit of an idiot for not doing this sooner.
https://apps.apple.com/us/app/ublock-origin-lite/id674534269...
latexr 7 hours ago
> I feel like a bit of an idiot for not doing this sooner.
Don’t beat yourself up, uBlock Origin on iOS is only four months old.
soundworlds an hour ago
I noticed my YouTube recommended searches seeming to change based on what Claude has just recommended me the other day. I do wonder how much of this data is being shared between the companies.
varenc 6 hours ago
For browsers that implement strict cookie partitioning, the privacy concern is moot. With this, the cookie jar that's used when chatgpt.com is a 3rd party site is completely separate for the jar used on the 1st party site. So your chatgpt.com account can't be linked to your ad views.
Since this has been standard ad tech for awhile, browsers have reacted to this to implement cookie partitioning for exactly these privacy reasons.
AznHisoka 9 hours ago
And the number of websites with ChatGPT ad trackers is on track to be doubled from last month.
according to Bloomberry: https://bloomberry.com/data/chatgpt-ads/
Avshalom 9 hours ago
Yuuup. tracking consumers and finding spending correlations to exploit was the entire reason for the "Data Science" and "ML" pushes that got us here.
arealaccount 4 hours ago
I thought 3rd party cookies were blocked on like every major browser, since like forever ago. Is Chrome still allowing this?
kylecazar 4 hours ago
Chrome still allows it. Safari and Firefox don't.
ryankrage77 3 hours ago
I've got Pi-hole and uBlock, use Firefox container tabs to isolate certain sites, and Firefox still reports it blocked over 2800 trackers this month alone. I wonder how many are still getting through.
bcorigliano 4 hours ago
This is bad. Like really SUPER bad. Firstly, for professional work you want your AI clean of useless context.
Secondly, you also want your AI "unbiased". I know unbiased is not a thing, but at least not as grotesquely biased as towards selling you something would be.
Thirdly, as many others are saying, the chamber of reflection effect deepens...
drnick1 9 hours ago
My DNS server (which uses Hagezi's excellent blacklists) returns NXDOMAIN for bzr.openai.com. Serves OpenAI right.
jsrozner 9 hours ago
I keep meaning to set this up but haven't. What's the simplest best setup for my own DNS blocker?
drnick1 9 hours ago
The easiest off-the-shelf option would be a router running OpenWrt. IIRC, it natively uses dnsmasq, and the relevant blacklists can be obtained from here:
https://github.com/hagezi/dns-blocklists
My own setup is DIY: a Debian box running Unbound (recursive DNS) with the RPZ blacklists from above. This gets rid of the upstream DNS service such as the ISP's completely, and prevents tampering or censorship.
kuerbel 9 hours ago
Hmmm Pihole I guess. Runs on a pi zero (1 or 2 but 2 is better ofc)
eevahr 9 hours ago
For simplicity I highly recommend https://nextdns.io. Supports most devices, and probably most, if not all, well known blacklists.
anygivnthursday 7 hours ago
For a home network network pihole or unbound also supports blocklists (bundled with opnsense for example if you also want a firewall). For Android, I use Rethink with Hagezi blocklists, so they block also when I am on mobile data (it is vpn based).
BCM43 9 hours ago
This has been around since at least April: https://www.adexchanger.com/daily-news-roundup/the-openai-pi...
nelsonfigueroa 6 hours ago
why is OpenAI wasting their efforts on implementing ads if they are apparently close to AGI?
jrflo 6 hours ago
I would assume the skill set for implementing ads is quite different than the skill set for developing new models, so it’s quite reasonable to expect different teams are working on each
smokel 6 hours ago
AGI will most likely have told them that this is the cheapest way to become rich.
emerongi 9 hours ago
https://tinfoil.sh/ - ultimately there is no guarantee that the LLM provider isn’t spying on you, but at least tinfoil claims to be unable to do so.
hbcondo714 9 hours ago
That is a nice sequence diagram[1]; I like how each endpoint param values are written out and the color distinctions. What tool did you use to create it?
[1] https://storage.ghost.io/c/b8/53/b853e3d4-3186-409d-9c7f-7da...
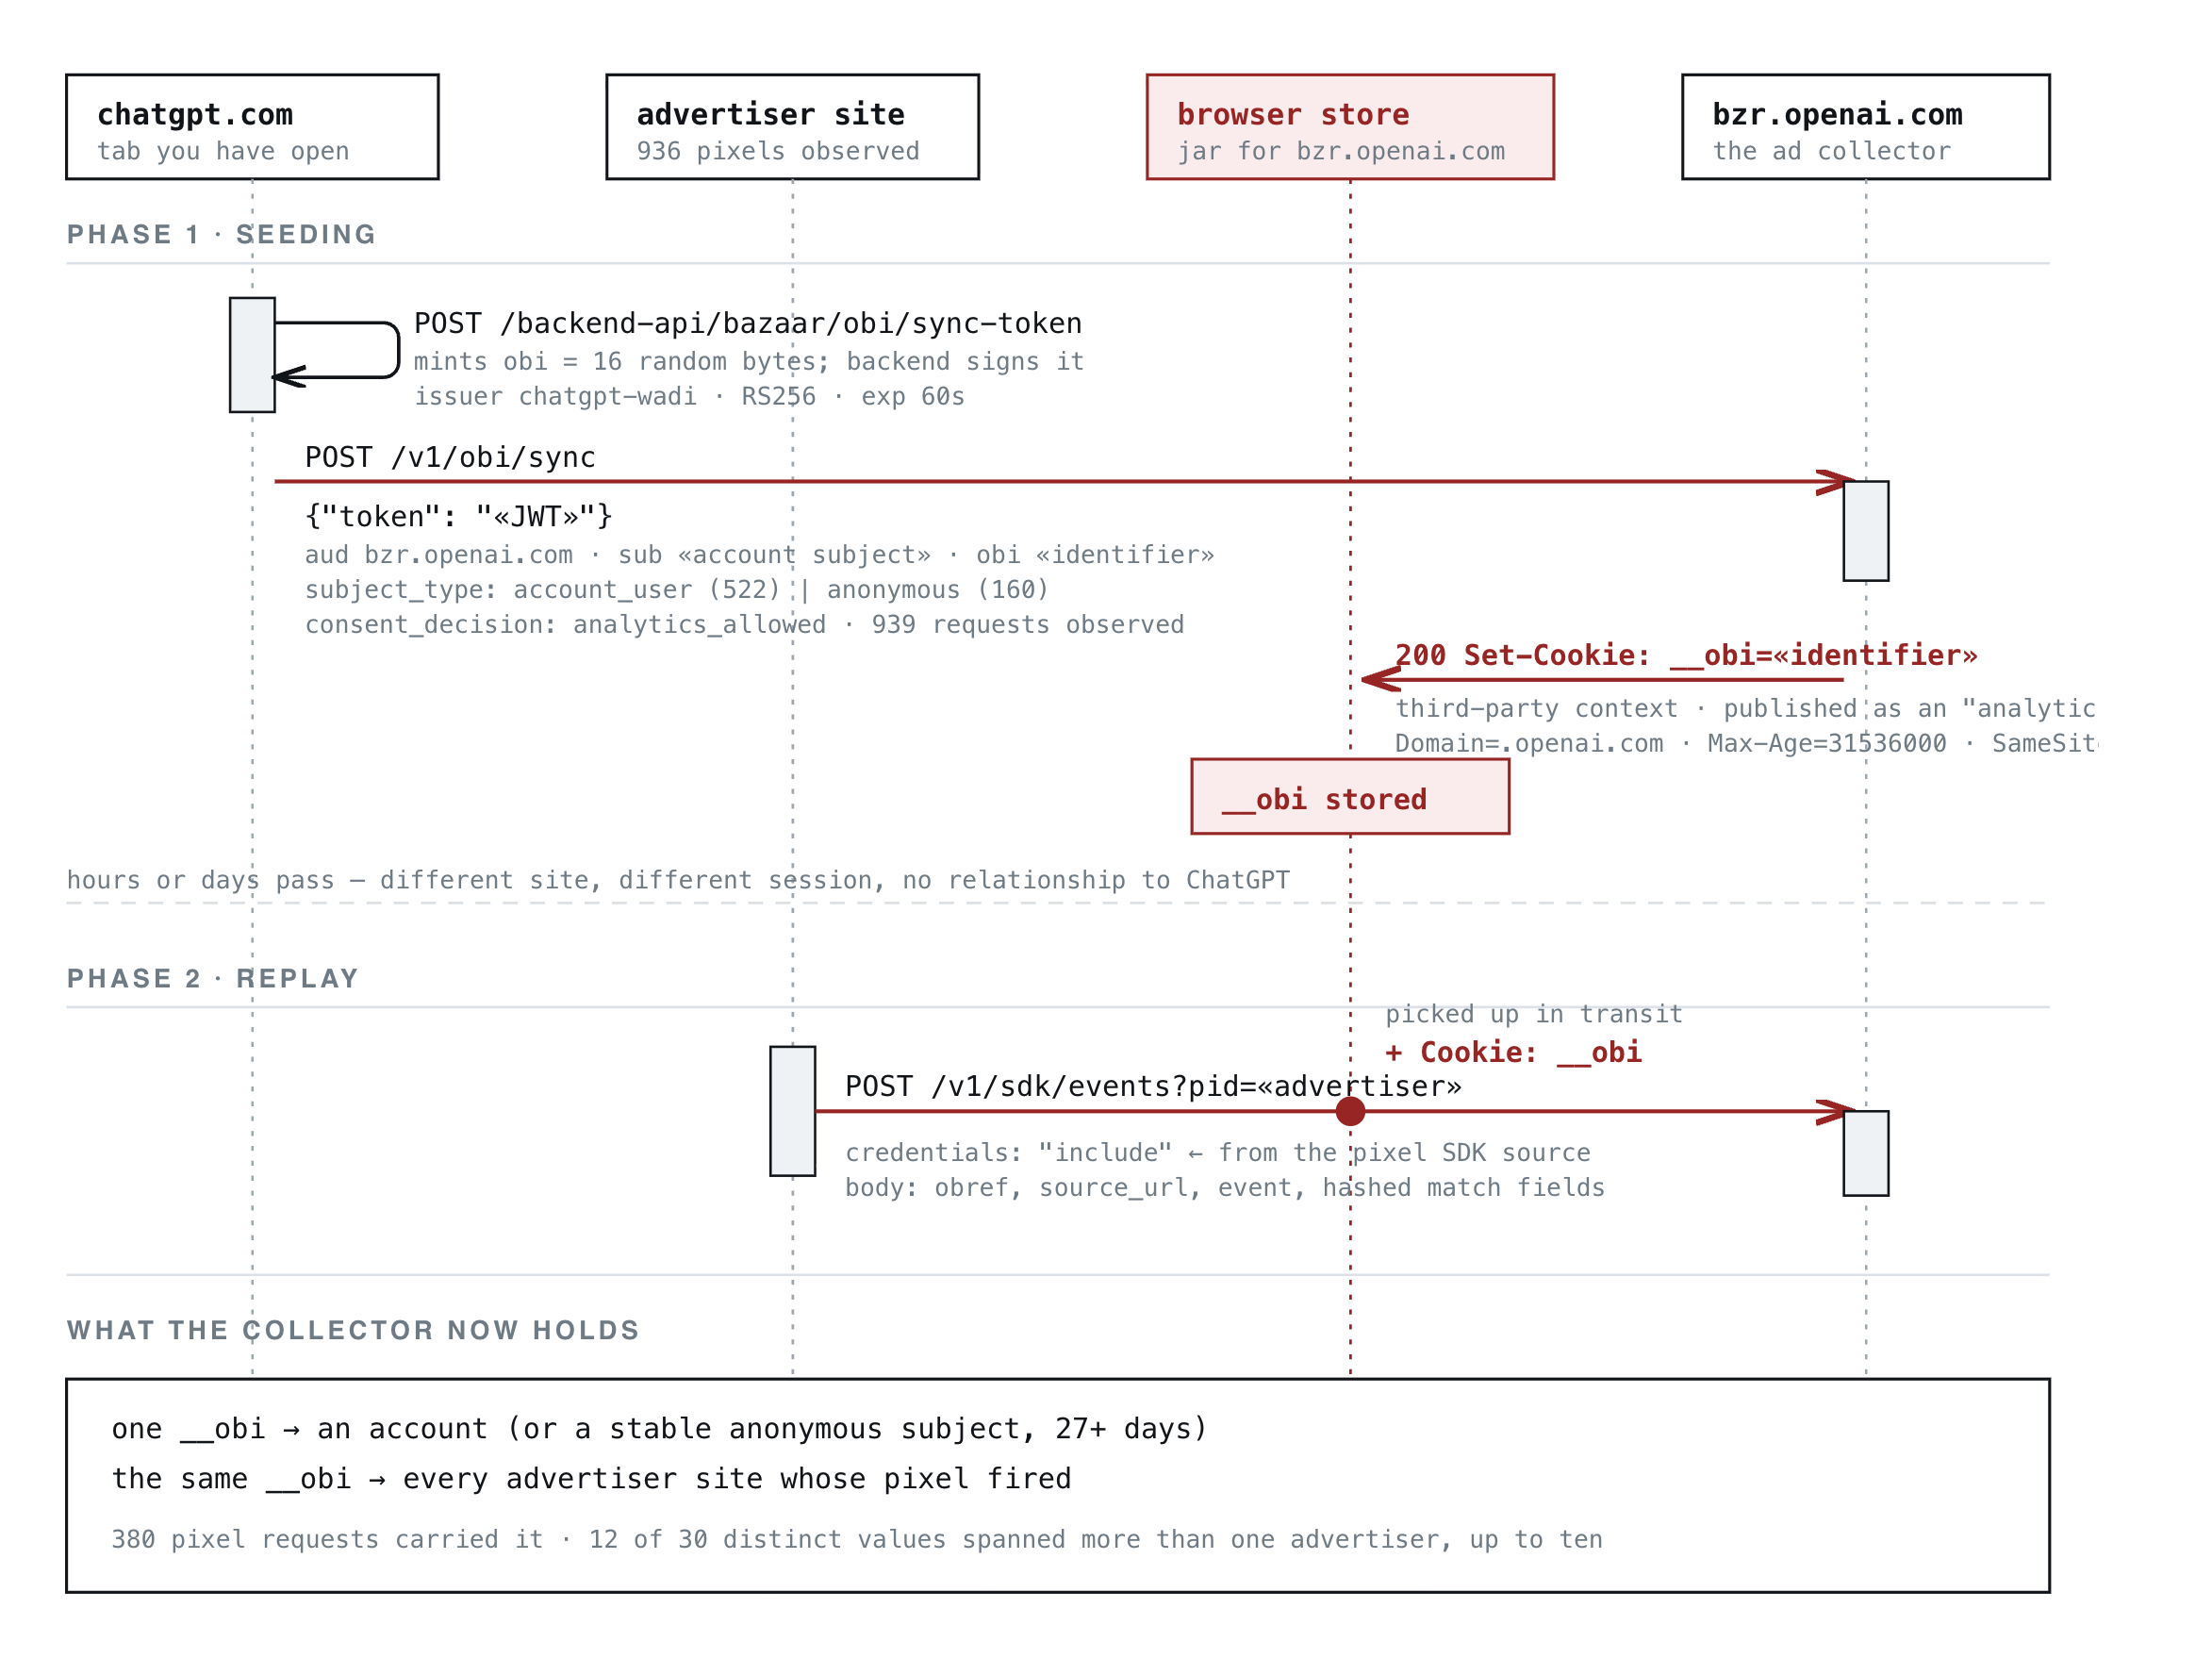
gpugreg 7 hours ago
I don't know the tool used here, but DeepSeek-V4.1-Flash with bash can create a somewhat similar SVG: https://asdf10.com/diagram.svg
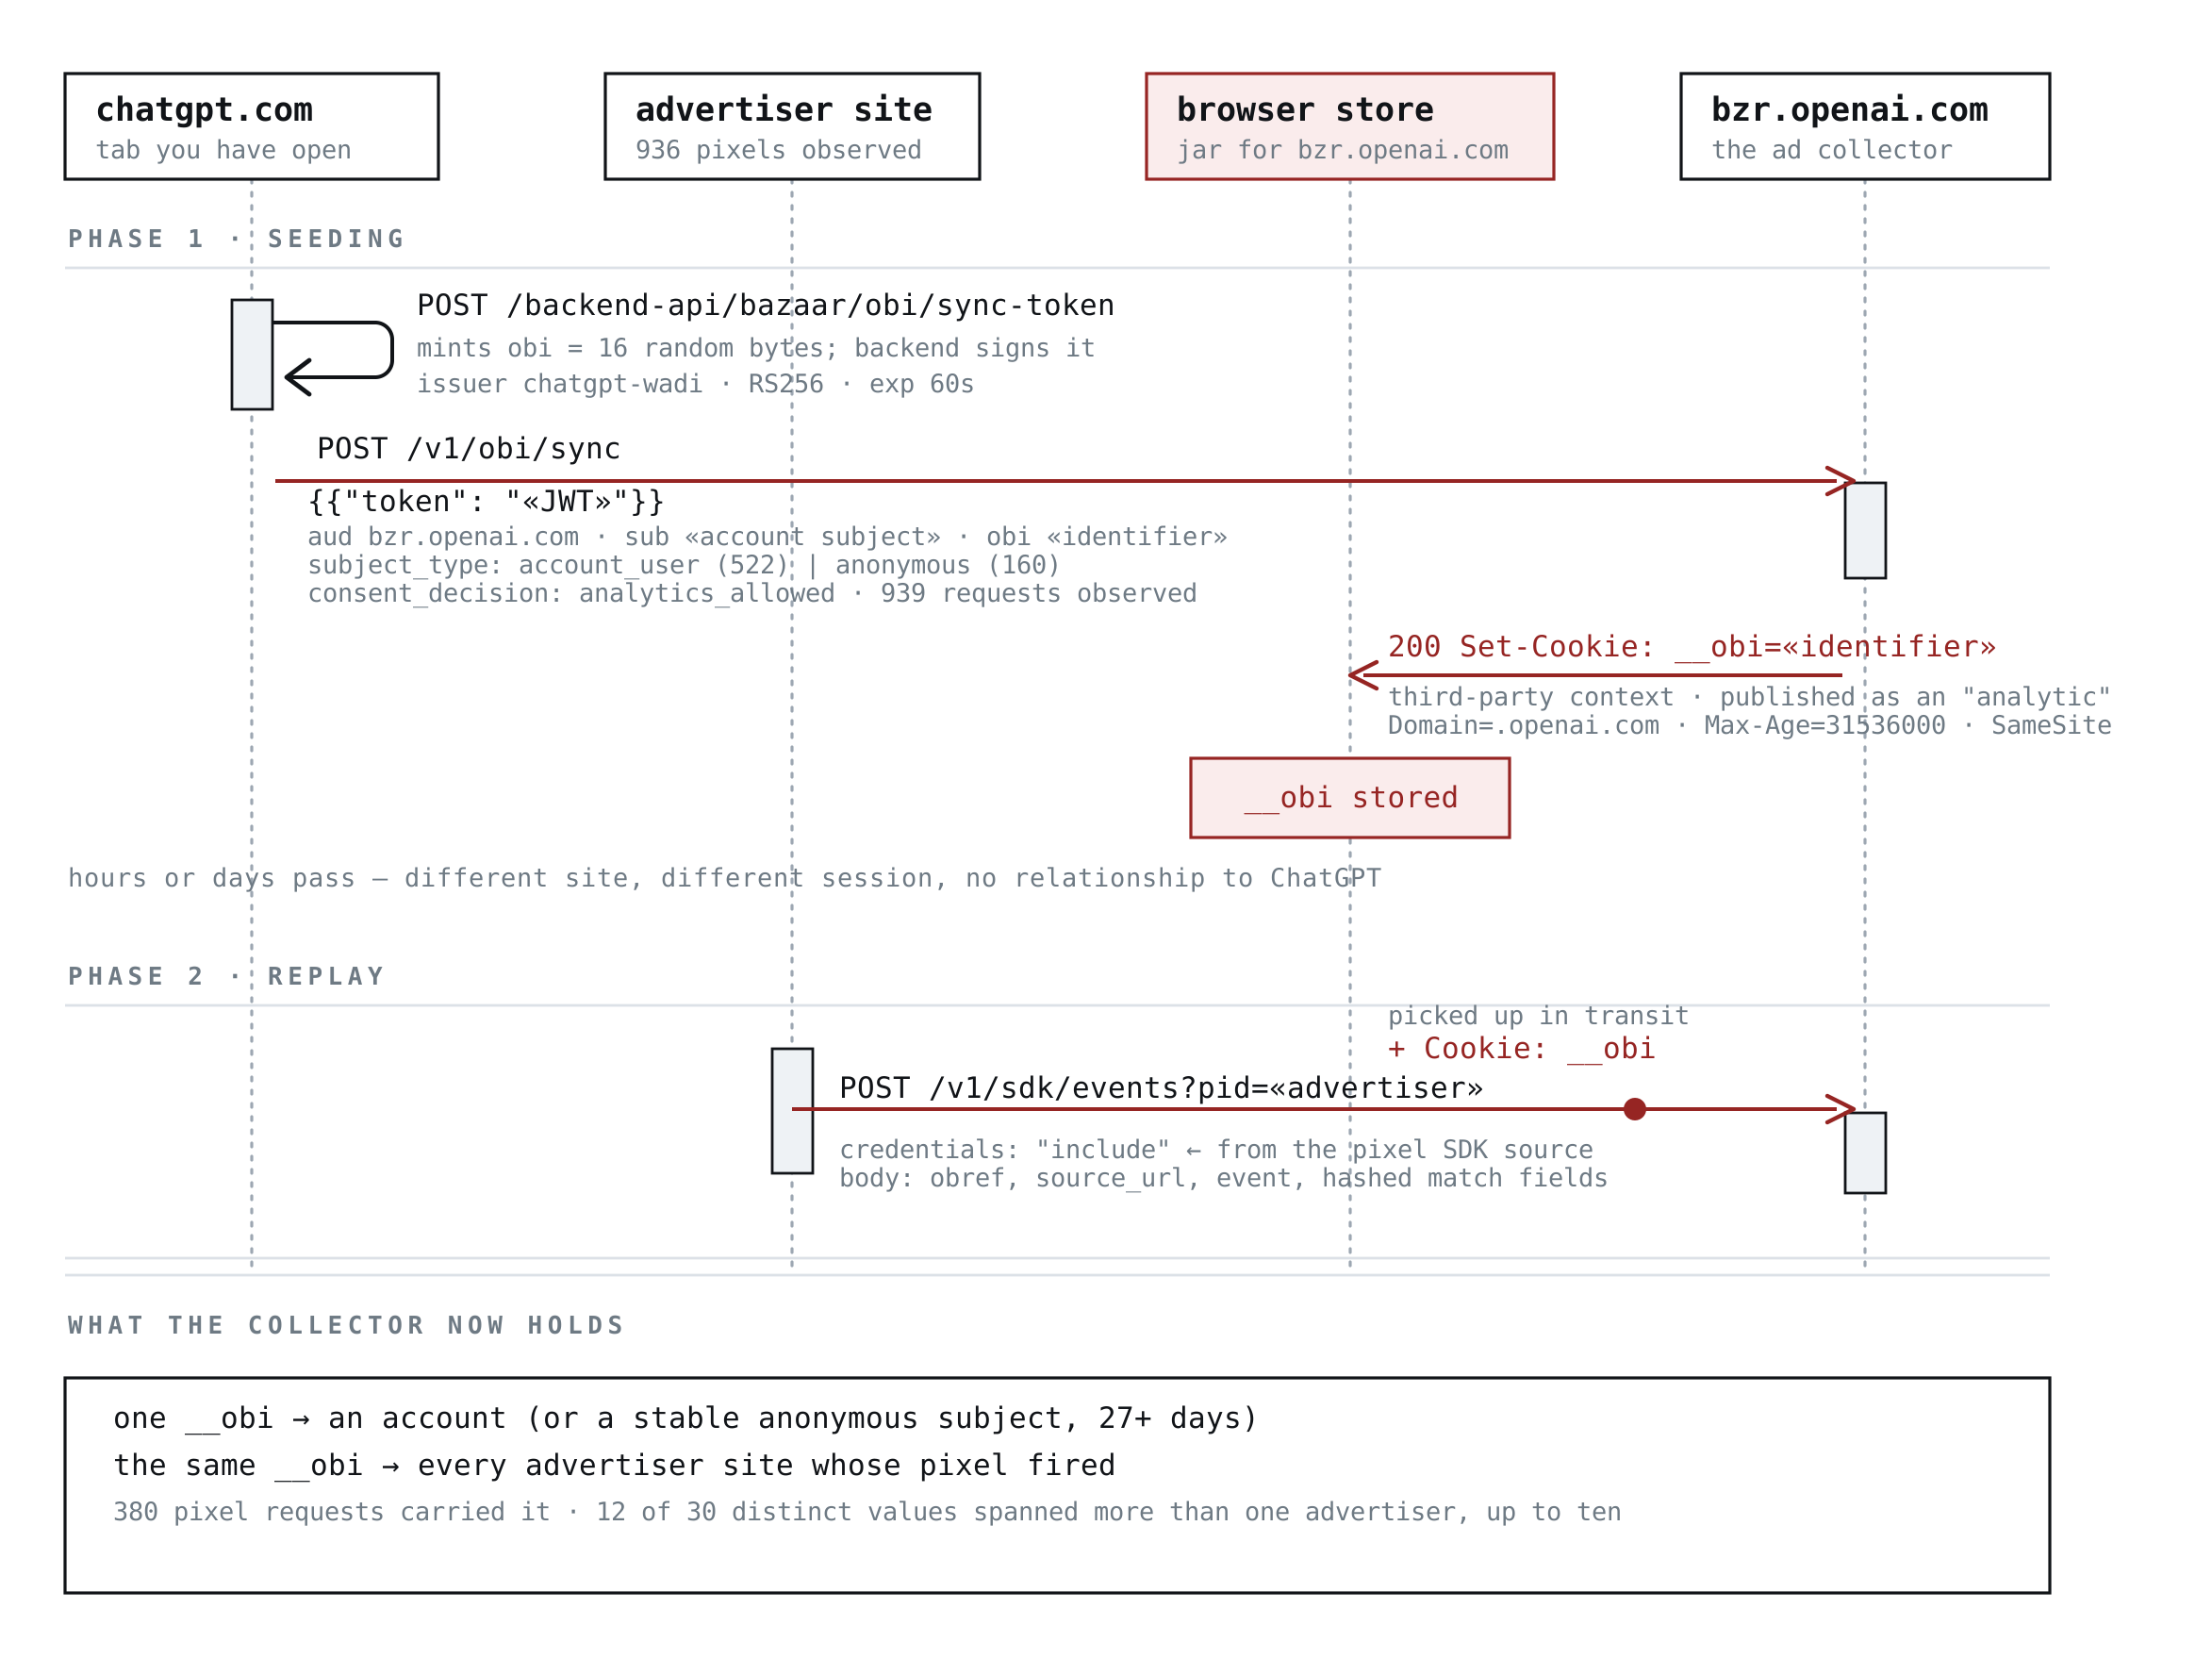
Disclaimer: I cut it off after a few minutes because I got impatient. It could have gotten closer if I waited longer.
DevKoala 8 hours ago
> The mechanism is standard adtech. What has no precedent is running it on an AI chat product.
Doesn’t Gemini or whatever Meta’s agent is do this too?